Browserless
Browserless is headless-browser infrastructure you can self-host via Docker or run managed — Puppeteer, Playwright, scrape, screenshot, and PDF APIs.
Overview
Browserless
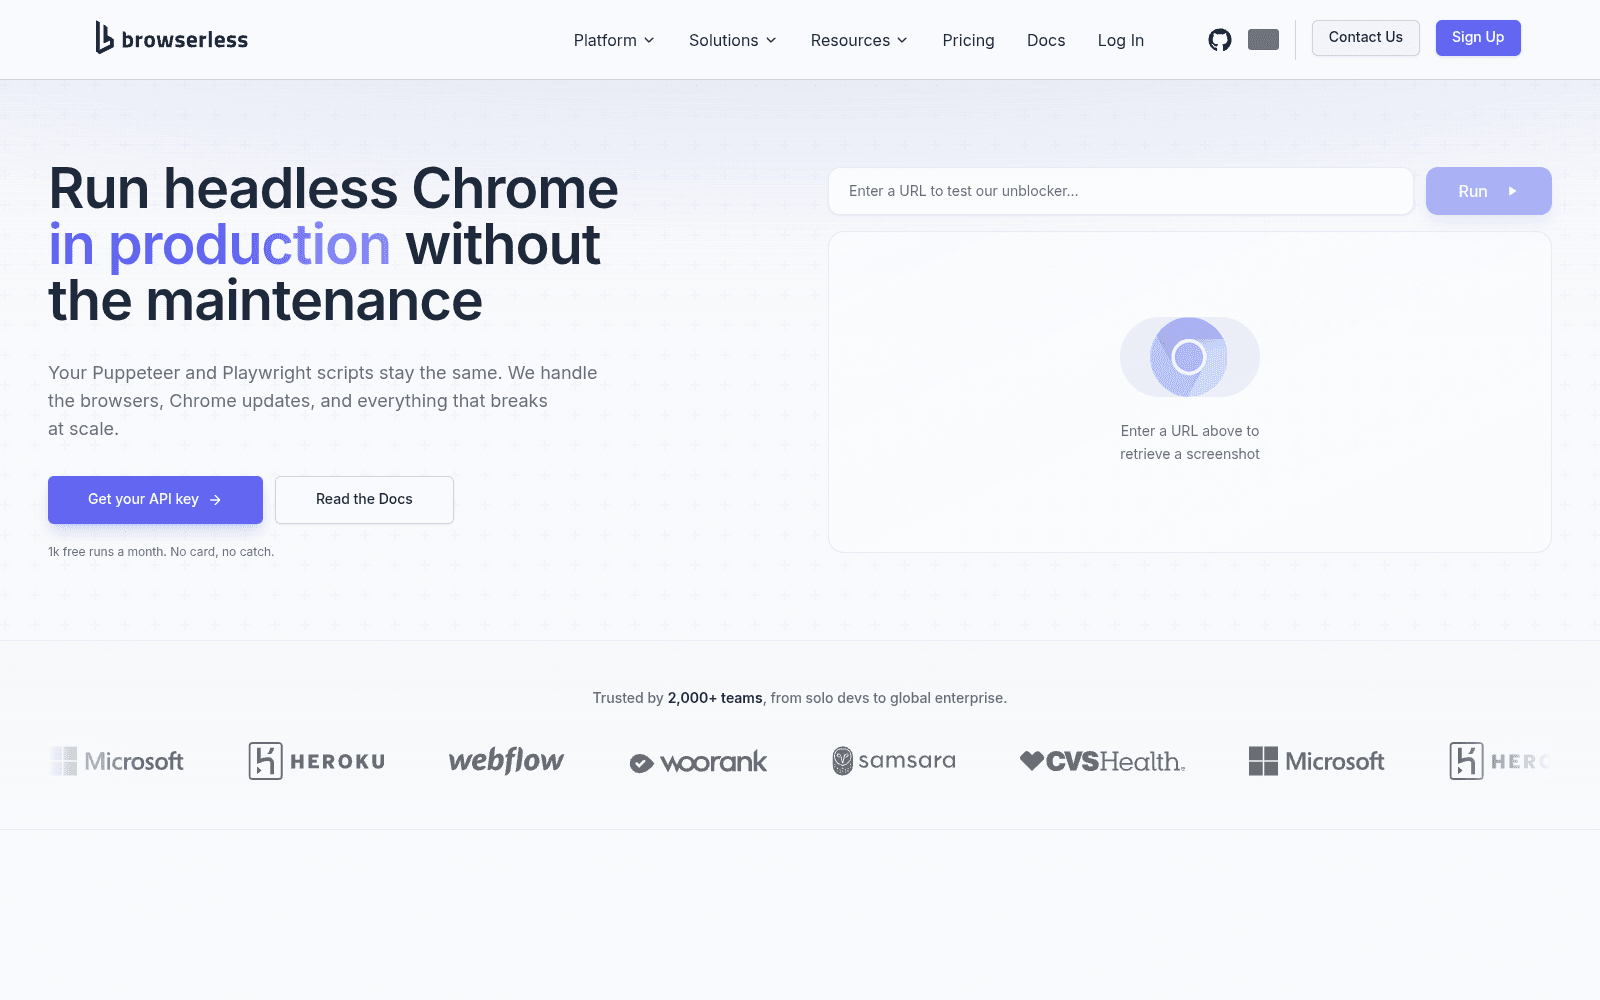
Browserless is headless-browser infrastructure that runs real Chrome, Firefox, and WebKit so you don't manage browser installs, crashes, or scaling yourself. You connect existing Puppeteer, Playwright, or Selenium scripts over a WebSocket endpoint, or call REST APIs for one-shot scrapes, screenshots, and PDFs. What sets Browserless apart in 2026 is the deployment choice: run it on the managed cloud pool, or self-host the Docker image on your own infrastructure when compliance or data control requires it. In market since around 2017 and bootstrapped to roughly $4M ARR, Browserless is the established self-host option in this category.
Production credibility: Founded by Joel Griffith and in market since around 2017; bootstrapped with no outside funding, self-reported at roughly $4M ARR in 2025. The core browserless/browserless repo has about 13.3K GitHub stars and is source-available under a dual SSPL-1.0 or commercial license — free for non-commercial and open-source use, paid commercial license for business use. Ships official Docker images, an MCP server for AI agents, and integrations with Stagehand, LangChain, n8n, Make, and Zapier.
Key Features
- Self-host via official Docker images (Chromium, Firefox, WebKit) on your own infrastructure
- Managed cloud browser pool with no infrastructure to run
- Connect existing Puppeteer, Playwright, or Selenium scripts over a WebSocket CDP endpoint
- REST APIs for one-shot /scrape, /screenshot, and /pdf jobs
- BrowserQL — a stealth-first GraphQL language for scripted automation and bot-detection bypass
- Built-in handling for Cloudflare, reCAPTCHA, and Amazon WAF, plus metered residential/datacenter proxies
- Official MCP server plus session persistence and reconnect for AI-agent workflows
Ideal Use Case
Teams that need headless browsers for web scraping, automated screenshots, PDF generation, or agent automation and want the option to self-host — particularly in regulated or compliance-sensitive environments where running the browser pool on their own infrastructure matters more than a fully managed service.
How Browserless differentiates
Browserbase, Hyperbrowser, and Steel are newer, agent-first managed platforms. Browserless predates them — it has been in market since around 2017, is bootstrapped rather than VC-funded, and treats self-hosting as a first-class path through its Docker images. The trade-off is the license: the core is source-available under SSPL or a paid commercial license, not permissive MIT or Apache, so commercial self-hosting requires a paid license. For teams that need to run browser infrastructure inside their own perimeter for compliance or cost control, that self-host story is the reason to pick Browserless over a managed-only competitor.
FAQ
Q: What is Browserless? A: Browserless is headless-browser infrastructure that runs Chrome, Firefox, and WebKit for scraping, screenshots, PDFs, and AI-agent automation. You connect Puppeteer, Playwright, or Selenium over WebSocket, or call REST APIs.
Q: Can I self-host Browserless? A: Yes — self-hosting is the core use case. Pull the official Docker images and run the browser pool on your own infrastructure, which is why teams pick it for compliance or infrastructure control.
Q: Is Browserless open source? A: It is source-available, not permissively licensed. The core is dual-licensed under SSPL-1.0 or a paid Browserless commercial license — free for non-commercial and open-source use, paid for commercial use.
Q: Browserless vs Browserbase? A: Browserless is the older, bootstrapped, self-host-friendly option with Docker images, REST APIs, and BrowserQL. Browserbase is the newer, VC-funded, agent-first managed platform. Pick Browserless when you need to run the infrastructure yourself.
Q: Does Browserless handle bot detection and CAPTCHAs? A: Yes — through its BrowserQL stealth language, an /unblock endpoint, residential proxies, and built-in handling for Cloudflare, reCAPTCHA, and Amazon WAF. Proxy traffic and CAPTCHA solves are metered.
tl;dr
Browserless is the self-host option for browser infrastructure — run headless Chrome, Firefox, and WebKit via Docker on your own machines, or use the managed cloud. Puppeteer, Playwright, Selenium over WebSocket, REST scrape/screenshot/PDF APIs, plus BrowserQL stealth and an MCP server. Bootstrapped since ~2017, ~13.3K GitHub stars, source-available under SSPL or commercial license. The compliance- and infra-control pick versus Browserbase, Steel, and Hyperbrowser.
Why Use Browserless
FAQ
Editorial Review
Our take on Browserless.
The most actively maintained headless-browser service we track, with an open-source core you can self-host and a licence that decides whether you may; the team behind it is small enough to be a factor in its own right.
What works
- Weekly open-source releases and a self-hostable Docker image
- Works with existing Puppeteer, Playwright and Selenium code plus REST and MCP
- Privacy policy states page content is not stored or resold
What doesn't
- Bootstrapped team of under ten people behind a widely used service
- SSPL licence bars commercial self-hosting without paying; stealth use carries target-site risk
Browserless runs real Chrome, Firefox and WebKit in the cloud so you do not manage browser installs, crashes or scaling. You point existing Puppeteer, Playwright or Selenium code at a WebSocket endpoint, or call REST endpoints for one-shot screenshots, PDFs and scrapes; there is a GraphQL layer for harder, bot-protected targets and an MCP server so agents can drive a browser directly. Pricing is by usage, in blocks of browser time, with concurrency and session length rising by tier and an enterprise option for private or self-hosted deployments with SOC 2, GDPR and HIPAA paperwork.
The open-source project is the reason to trust it. Releases land most weeks, the repository is widely used, and the Docker image means you can run the same thing on your own hardware. Read the licence first: self-hosting is under the SSPL, so commercial use without a paid licence is not permitted, which is the point of the model.
Two cautions. The company is bootstrapped and, by third-party accounts, under ten people, so the bus factor is real even if the code is open. And the stealth features exist to get past sites that do not want automated visitors; that is your legal exposure, not Browserless's. The privacy policy is clear that page content is not stored or resold, which is the right answer for infrastructure that sees everything you fetch.
User Reviews
Similar Tools